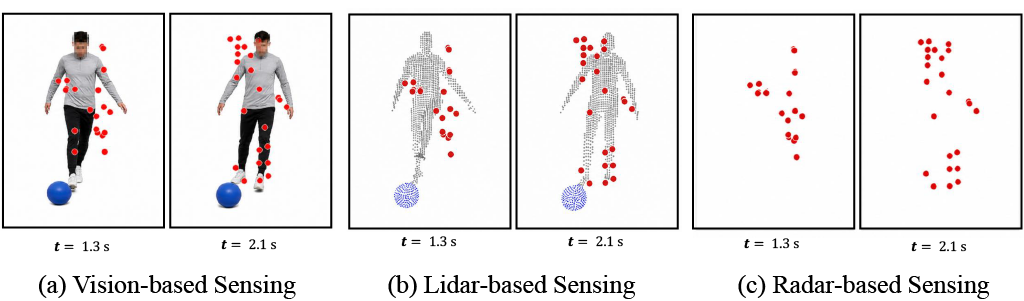
TL;DR: HIRaD infers hidden human-object interaction semantics from sparse mmWave radar by modeling observation-driven corrections to predicted body motion, without directly detecting objects.
Abstract
Millimeter-wave radar point clouds provide a visually privacy-preserving representation for human motion analysis, but object-related interactions remain difficult to describe because the object evidence that defines the interaction is not always separable or consistently observable in sparse radar returns. We address this problem without direct object detection. Instead, we infer hidden interaction semantics from the temporal structure of observation-conditioned corrections to predicted body motion, motivated by the view that object affordances shape how the body moves. To this end, we propose HIRaD, a radar semantic sensing framework that organizes sparse radar returns into a predictive node-structured latent state of local motion carriers. It represents interaction-relevant cues as corrective residual trajectories between a motion-continuation prior and an observation-conditioned posterior, and compresses these trajectories into a language-aligned semantic bottleneck. A structured prefix conditions a frozen autoregressive language model on both the semantic bottleneck and node-level motion summaries, separating compact interaction-level cues from node-level motion evidence. Experiments show that our proposed method improves radar captioning and interaction understanding under weak object observability over strong baselines, while ablations validate the importance of radar-conditioned prefixing, latent state representation, and residual trajectory modeling.
Contributions
- [Contribution one.]
- [Contribution two.]
- [Contribution three.]
Method
[Short overview of the pipeline: radar input, latent dynamics, residual, captioner.]
[Component name]
[A paragraph per key component. Duplicate this h3 + p pair as needed.]
Results
[One paragraph summarising the main quantitative finding.]
| Method | BLEU-4 | ROUGE-L | CIDEr | SPICE |
|---|---|---|---|---|
| [Baseline A] | – | – | – | – |
| [Baseline B] | – | – | – | – |
| [Baseline C] | – | – | – | – |
| HIRaD (ours) | – | – | – | – |
Qualitative examples
[One sentence on what these clips show.]
- Ground truth
- [Reference caption.]
- HIRaD
- [Predicted caption.]
- Ground truth
- [Reference caption.]
- HIRaD
- [Predicted caption.]
- Ground truth
- [Reference caption.]
- HIRaD
- [Predicted caption.]
Video
BibTeX
@inproceedings{[key]2026hirad,
  title     = {HIRaD: [Paper Title]},
  author    = {[Last, First] and [Last, First] and [Last, First]},
  booktitle = {[Venue]},
  year      = {2026}
}
Acknowledgements
[Funding, compute, and thanks.]